Series 2 parts Since
Locally fine-tuning Whisper and ASR models with Listenr
Fine-tuning speech models is a data problem. This series is about making that data: recording it, cleaning it, turning it into a dataset, and training on it, all on your own machine.
Fine-tuning ASR models these days has never been simpler - there are countless open models, libraries and tutorials to draw on. However, actually having data worth fine-tuning with is still a real challenge.
Open corpora exist and some of them are good, but they are mostly other people reading prepared sentences, and there are never enough of them saying the things you need said, not to mention the legal and ethical considerations of who's data it is you're using.
The ideal solution is then to create your own corpus of data, free of legal or moral issues. However, I found it was not that easy. Capturing audio, transcribing it, fixing the transcripts, and shaping the result into something a trainer will accept is slow, fiddly work that nobody wants to do twice.
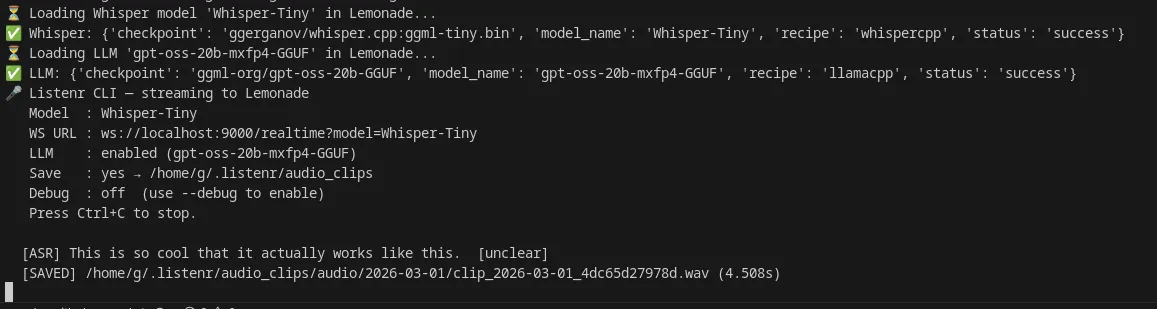
Hence why I created Listenr. It exists to make that part economical and repeatable. It listens, transcribes with existing ASR models, improves the transcript with a local LLM, and writes the result into a dataset a trainer can read. Everything can on your machine with modest compute requirements, and it plugs into the tools that already work like Hugging Face datasets and standard model formats, rather than inventing its own.
This series captures how I developed listenr to become a end to end fine-tuning project that (generally, mostly) just works.
All parts
- 01
Good speech data is the hard part
Whisper is impressive and its vocabulary stopped in 2023. Fine-tuning fixes that, but only if you have high quality data, and getting that is the part nobody wants to do.
- 02
Fine-tuning Whisper models end to end with Listenr, good data, locally
A walkthrough of how to fine-tune Whisper end to end with Listenr, fully locally.